Web-based systems, from survey to deployment: data model, backend, interface, infrastructure.
If you cannot draw a system on one page, you do not understand it yet. I design institutional web platforms and retrieval systems, turning requirements into a bounded technical scope and that scope into something that runs and can be handed over.
current
ATILIM University
field
Full stack → Backend · RAG
scope
Institutional
span
20+ years
stack
php · laravel · nuxt · pgvector
About
sheet 02
A web systems architect who designs web-based systems from survey to deployment, and builds everything between where a request arrives and where infrastructure takes over.
I spent 20+ years in IT and have been developing professionally since 2019. That order is not an accident. Coming to software after systems, networking and infrastructure makes it easier to see where today's decision lands three years from now. I started as a full stack web developer; today the weight is on backend architecture and RAG systems.
At Atılım University I work as Web Development Specialist within the Directorate of Corporate Communications and Promotion. The scope is not only code: I manage the content of the institutional site, set up and run the faculty and administrative unit sites, enter academic staff information, and support the research assistants and academics responsible for their department's web pages.
What decides the outcome is often not the code but keeping the boundaries of responsibility clear: translating the content side's needs into a workable technical scope, agreeing the interface with the infrastructure side, and leaving the work documented and transferable.
direct responsibilityrun in coordinationScale 1:1 · unit of measure: responsibility
Interfaces
sheet 03
On an institutional web platform, knowing where the work starts and stops decides more than the code does. I have two boundaries: the content side a request arrives from, and the point where infrastructure takes over.
Upper boundary
Directorate of Corporate Communications and Promotion
crosses the boundary
Publishing needs, content calendar, corporate identity rules, campaign and promotion requests.
Lower boundary
IT and Infrastructure
crosses the boundary
Server and certificate management, access rights, backups, security requirements.
Requests usually arrive as needs with a short turnaround: a campaign page, an application flow, a small service. Because the interface, application, data and deployment sit in one pair of hands, going from a requirement to a running version normally takes a single round of coordination.
How the work runs
01
Turning a request into scope
Work does not start until a request becomes a feasible technical scope with a clear boundary.
02
Keeping revisions traceable
Change requests are recorded; which decision was taken when, and why, can be read back later.
03
Leaving it transferable
Setup, dependencies and operating steps are documented, so the work does not depend on one person.
04
Planning maintenance
Version upgrades and maintenance windows are agreed so they do not collide with the publishing calendar.
Skills
sheet 04
backend
php
laravel
postgresql
mysql
rest api
filament
retrieval
pgvector
embeddings
rag pipeline
llm api
frontend
vue.js
nuxt
blade
tailwind
javascript
devops
linux
nginx
ssh
cloudflare
tools
git
wordpress
Retrieval
sheet 05
This drawing is a section through one installation: a source-citing assistant built over a bilingual institutional corpus of roughly seven thousand pages. The order of stages is similar in most RAG systems; what happens inside each stage is decided again for every data source, sector, language set and error tolerance. The details below are the decisions made for this installation, not a recipe.
The two lanes run separately: the offline one indexes the content, the online one drops the query into that same index. Most of the cost sits in the first lane; all of the latency sits in the second.
detail 01
Source
what
Content pages and structural modules from the CMS are gathered into a single corpus.
in this installation
Read directly from the database, selected by publication status and language; table, accordion and tab modules are flattened to plain text.
decision
Unpublished pages are excluded; archive pages were producing answers as if they were current, which the evaluation showed.
where it changes
If the source is a PDF archive, a ticketing system or a product catalogue, the collection layer is built entirely differently.
detail 02
Extraction and normalisation
what
Text is extracted; whitespace, heading hierarchy and character set are corrected.
in this installation
The heading chain is attached to every chunk as context.
decision
Content under 100 characters does not enter the index; roughly a third of the corpus was meaningless short records.
where it changes
In table-heavy data (price lists, technical dimensions) the table structure is preserved rather than flattened to text.
detail 03
Chunking
what
Text is split so that units of meaning stay intact.
in this installation
Overlapping chunks that respect heading boundaries; size set by the embedding model's limit.
decision
Attaching the heading chain to each chunk; a bare paragraph lost track of which unit it was about.
where it changes
In contracts or legislation the article is the chunk unit; in product data, the product record.
detail 04
Embedding
what
Each chunk is turned into a numeric vector.
in this installation
Gemini embedding-001, 768 dimensions; batch processing with per-chunk retry.
decision
The same model for query and document, with different task types; mixed use was shifting the scores.
where it changes
If data cannot leave the organisation, a local model (BGE-m3 was proposed for this installation's on-prem variant).
detail 05
Index
what
Vectors are kept in a queryable index.
in this installation
PostgreSQL + pgvector, HNSW with cosine; language and content-type columns, incremental re-indexing.
decision
pgvector instead of a separate vector database; the content already lives in Postgres, so one service, the same backups and the same permission model.
where it changes
With millions of chunks or a multi-tenant setup, a separate vector store (Qdrant in the on-prem variant).
detail 06
Query
what
The question is turned into a vector through the same pipeline, and its language is detected.
in this installation
Language is a retrieval filter; institutional abbreviations are expanded.
decision
Filtering by language at retrieval, not at generation; Turkish questions were pulling English sources and the citation link led to the wrong page.
where it changes
In a monolingual corpus this layer does not exist; for multi-step questions, query rewriting is added.
detail 07
Retrieval and ranking
what
The nearest chunks are fetched, filtered and assembled into context.
in this installation
12 candidates, a similarity threshold, per-page deduplication, 6 sources; recency as a secondary criterion.
decision
Setting the threshold by measurement; the first threshold (0.35) never fired in practice, and only the evaluation showed that.
where it changes
Where precision is critical (legal, medical) a re-ranking model is added; a chat product uses a looser threshold.
detail 08
Generation and citation
what
The model produces an answer from the context, and the source pages are shown beneath it.
in this installation
Gemini Flash; abstaining on questions outside the sources; finish-reason and token-limit checks; sources shown as chips.
decision
Dropping the structured output schema; it turned out to be the cause of the broken Turkish characters. Three of five hypotheses were wrong, and a single-variable test found it.
where it changes
For internal use, citation gives way to triggering actions (MCP); in a public product the abstention threshold is set higher.
Alongside the system runs an evaluation pipeline: a fixed question set, trap questions and four-category labelling. Most of the decisions above came out of it.
Case studies
sheet 06
institutional web · content management
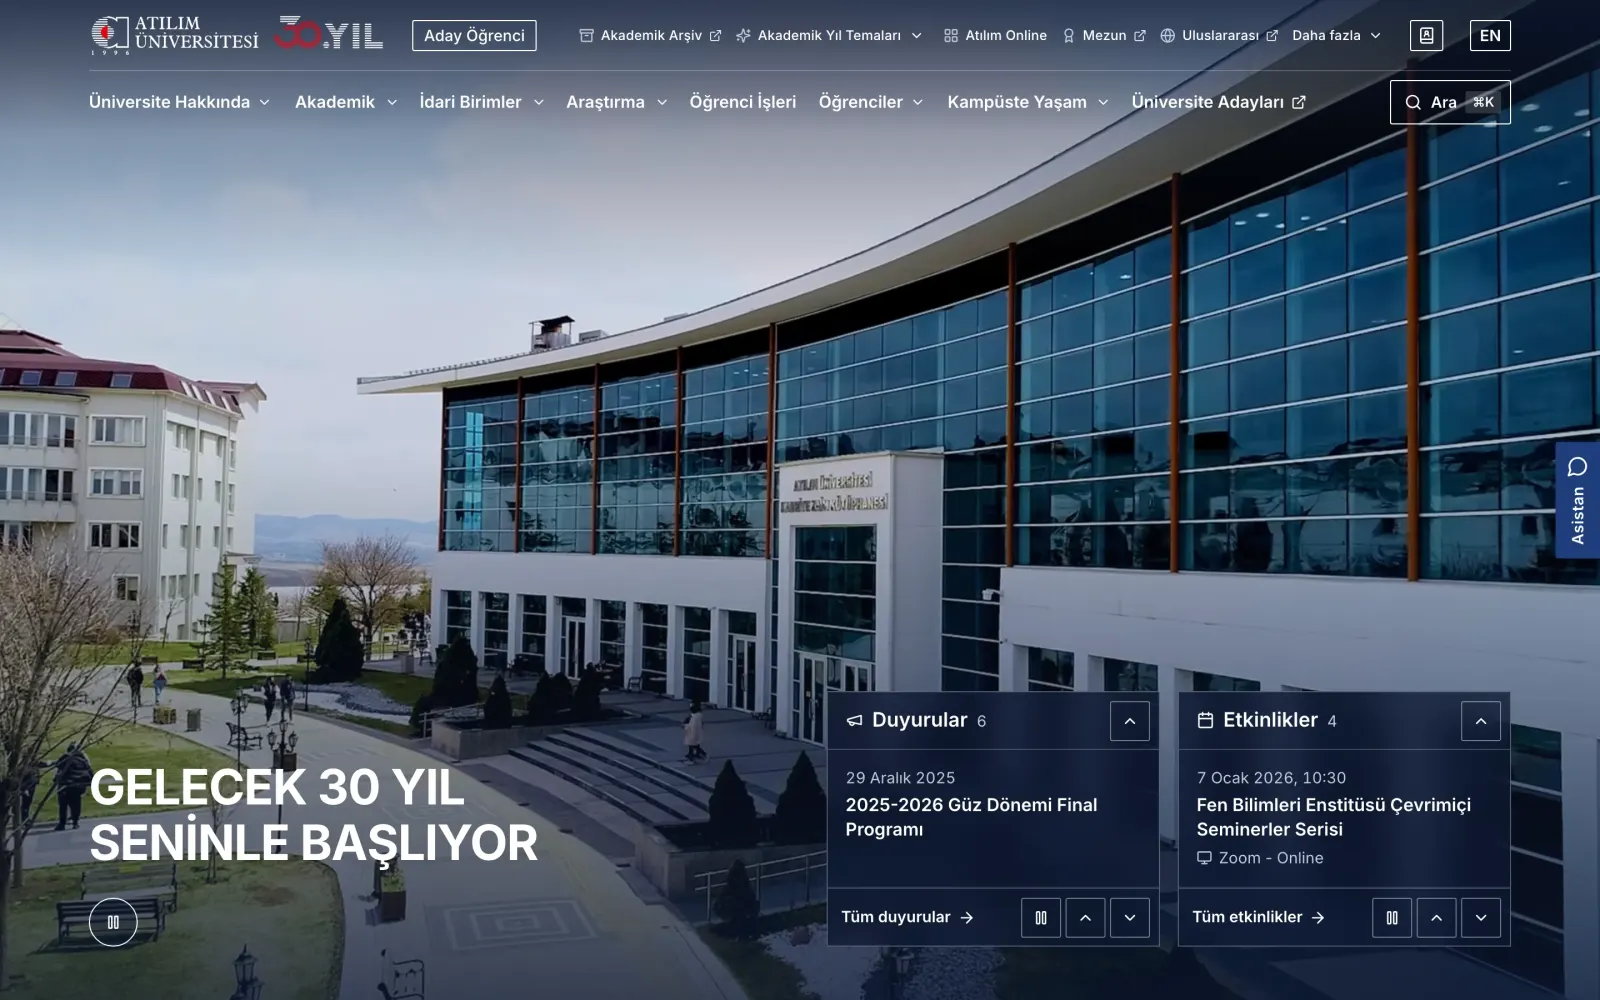
Atılım University Web and VectorCMS
Atılım University
01 / 03
problem
The site in use since 2018 had grown into a structure carrying the content of more than 300 units and getting harder to manage; tens of thousands of items and addresses linked from outside for years had to survive.
approach
Preserve first, then improve: a panel built for the institution (VectorCMS) and a new site with two themes (v2, v3), keeping old addresses and content IDs; every step with tests and a rehearsed migration.
outcome
A panel shaped by 12 roles and 151 permissions, a migration plan that carries about 25,000 items without loss, about 1,000 automated tests and a codebase that passed independent audits.
prospective student portal
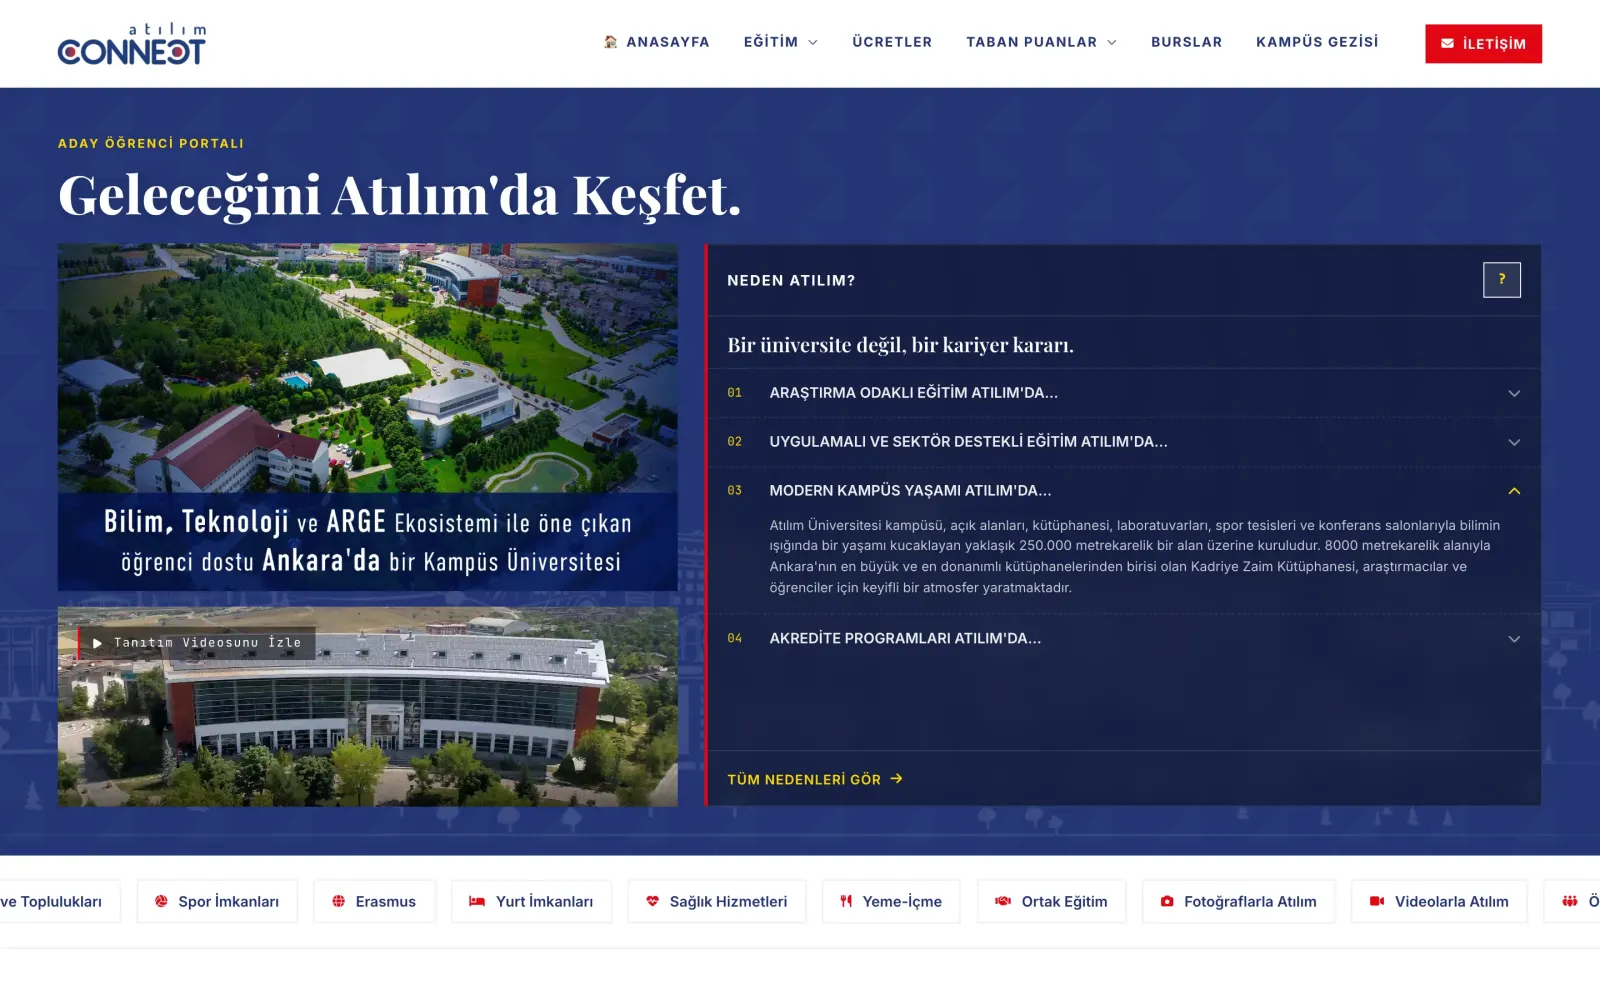
Atılım Connect
Atılım University
02 / 03
problem
The main site addressed the whole institution; there was no fast, easy-to-update channel focused on the prospective student's decision journey. Campus tour applications ran over the phone.
approach
Content separate from code, managed entirely from the panel; automation proposes, a person approves; unused modules are removed, versions kept current with tests.
outcome
Live since July 2025: an SMS-verified form engine, approved academic sync with the main site, analytics that write nothing without consent; day-to-day running is in the content team's hands.
request and workflow management
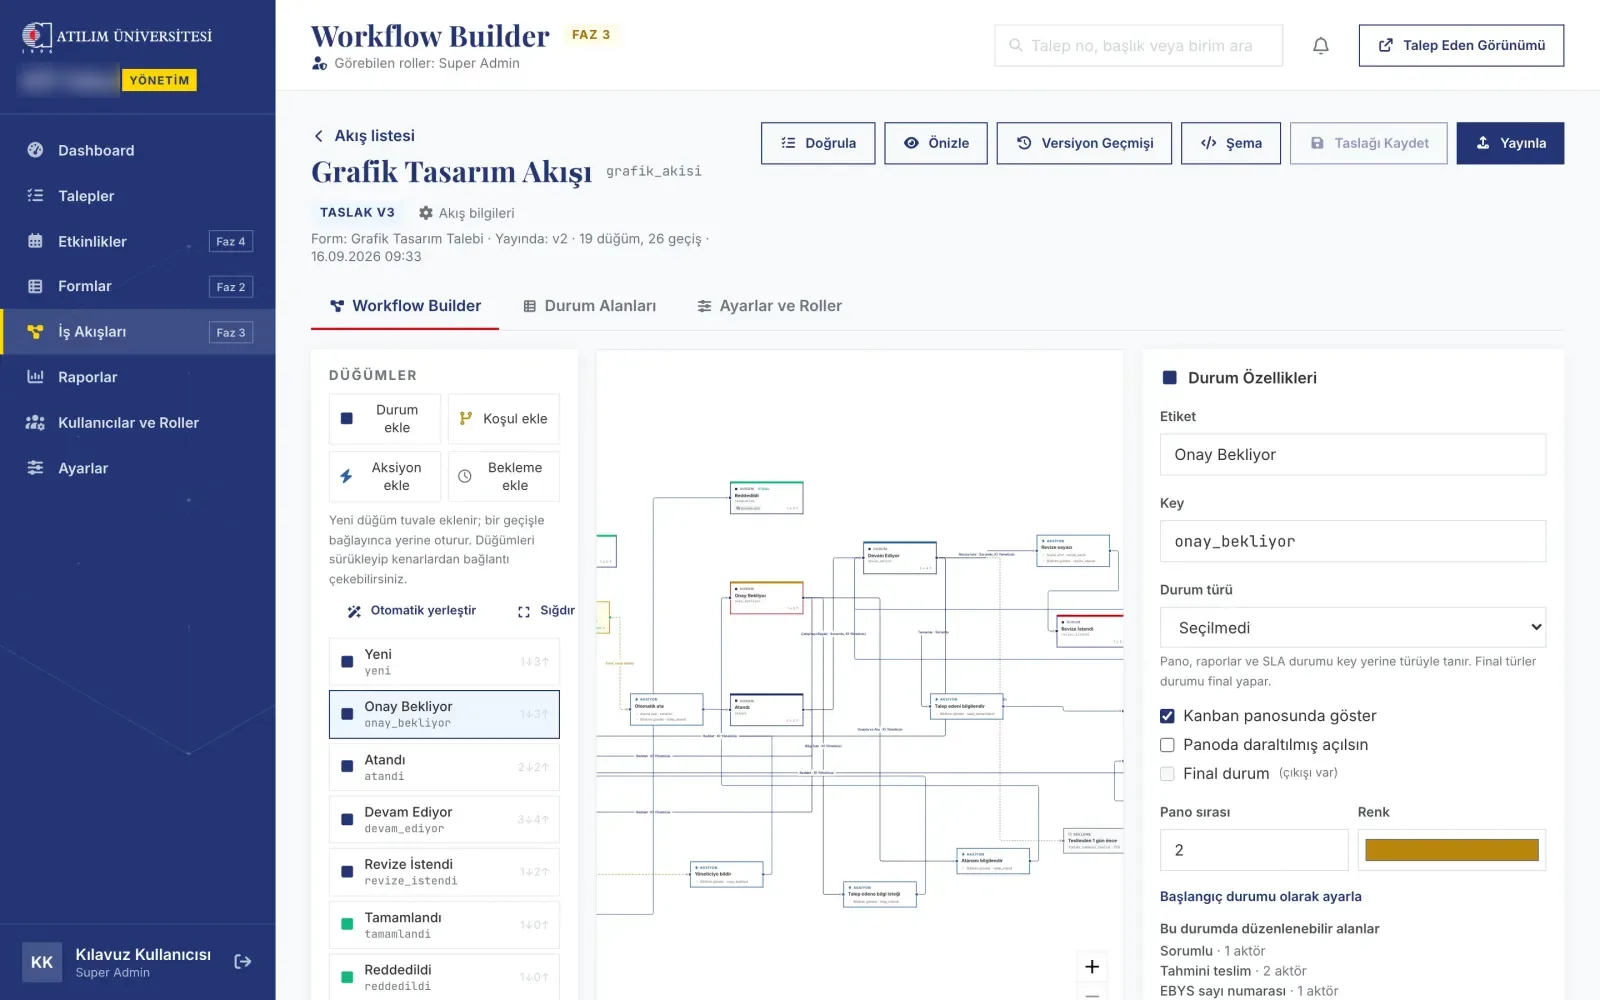
Corporate communications request and workflow system
Atılım University
internal testing · not yet live
03 / 03
problem
Requests arrived through scattered channels; which request was at which stage, and with whom it was waiting, could not be seen at a glance. Each request type needed different information and a different process.
approach
Format first, then code: forms and workflows are defined as schemas and changed with editors inside the panel; rules are the same on client and server; forms and workflows are versioned.
outcome
A transparent process for requesters, a dashboard, kanban and reports for management; a new request type or approval step can be added without waiting for a developer.
Breakdown
sheet 07
Every job is surveyed before it is priced. This is a summary of that survey: what came in, what was examined, which decisions were made. Methods are not explained; decisions and their reasons are. Jobs that stayed at proposal stage or were declined are here too, because saying no is also a decision.
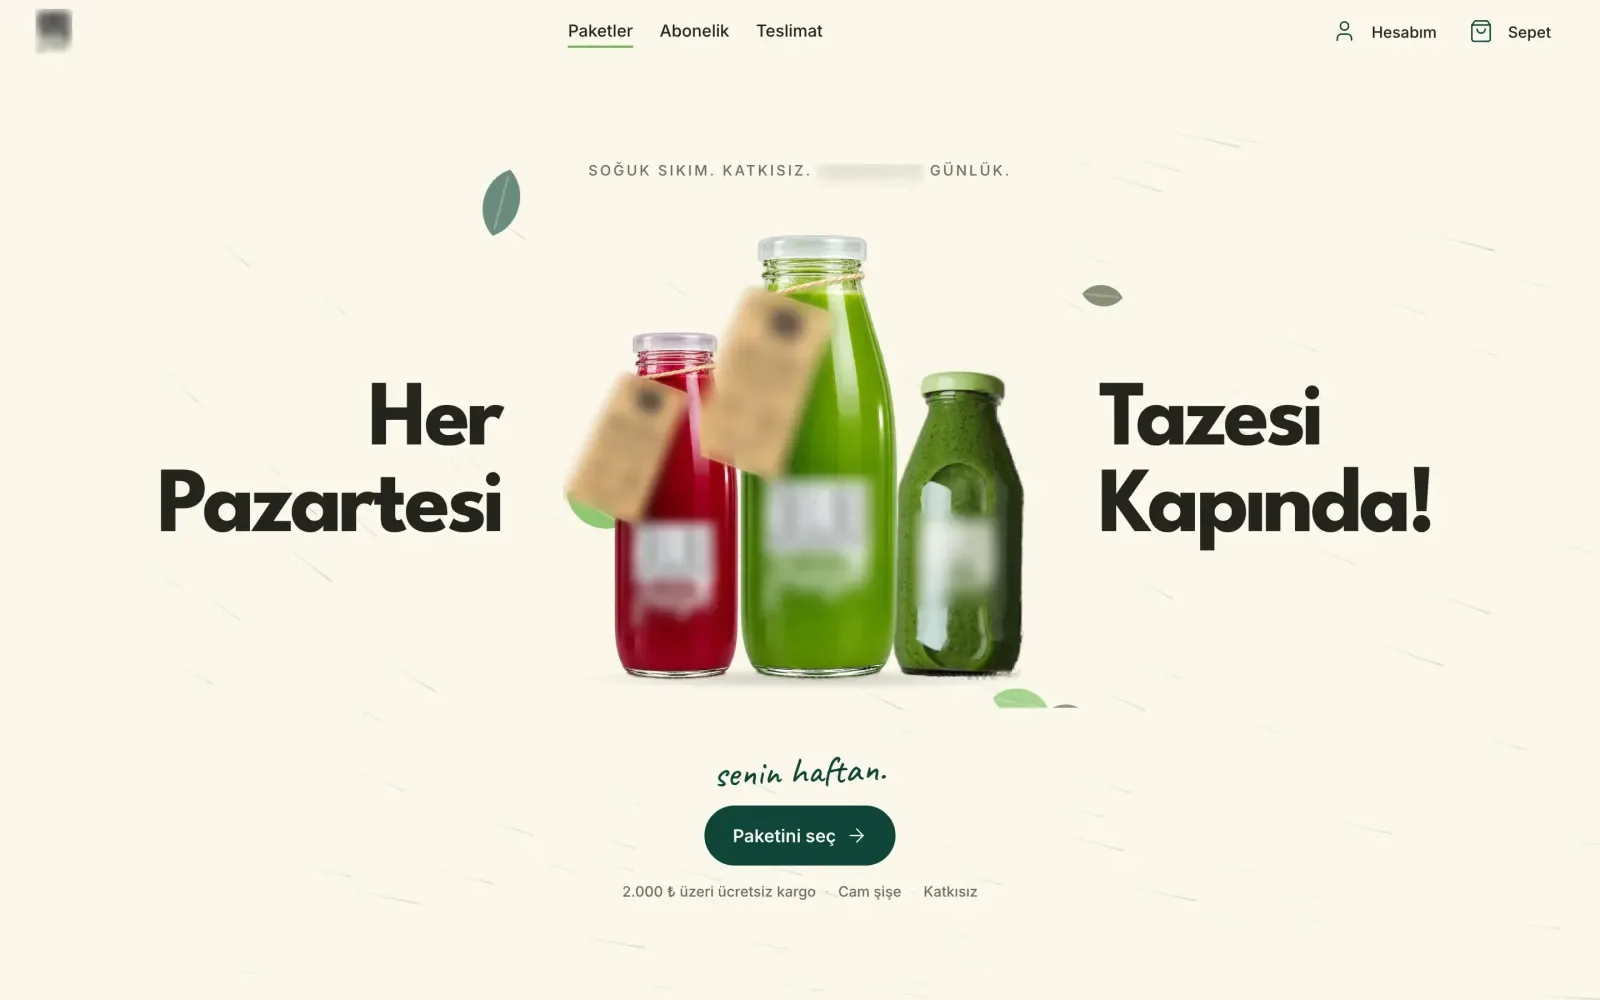
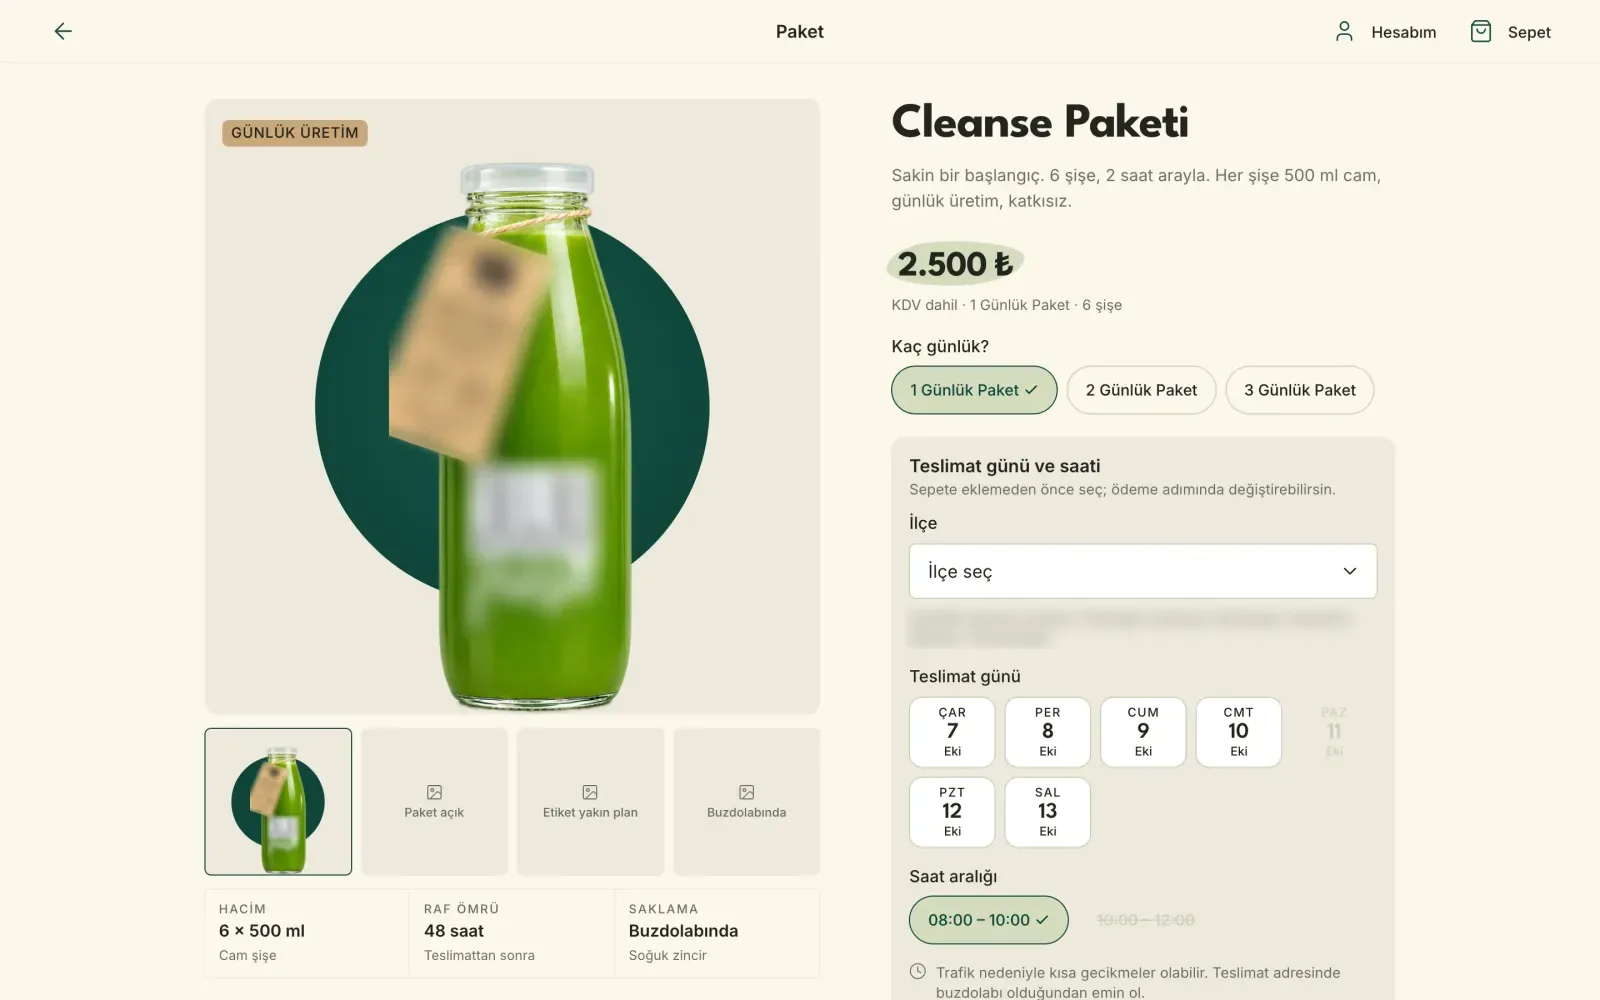
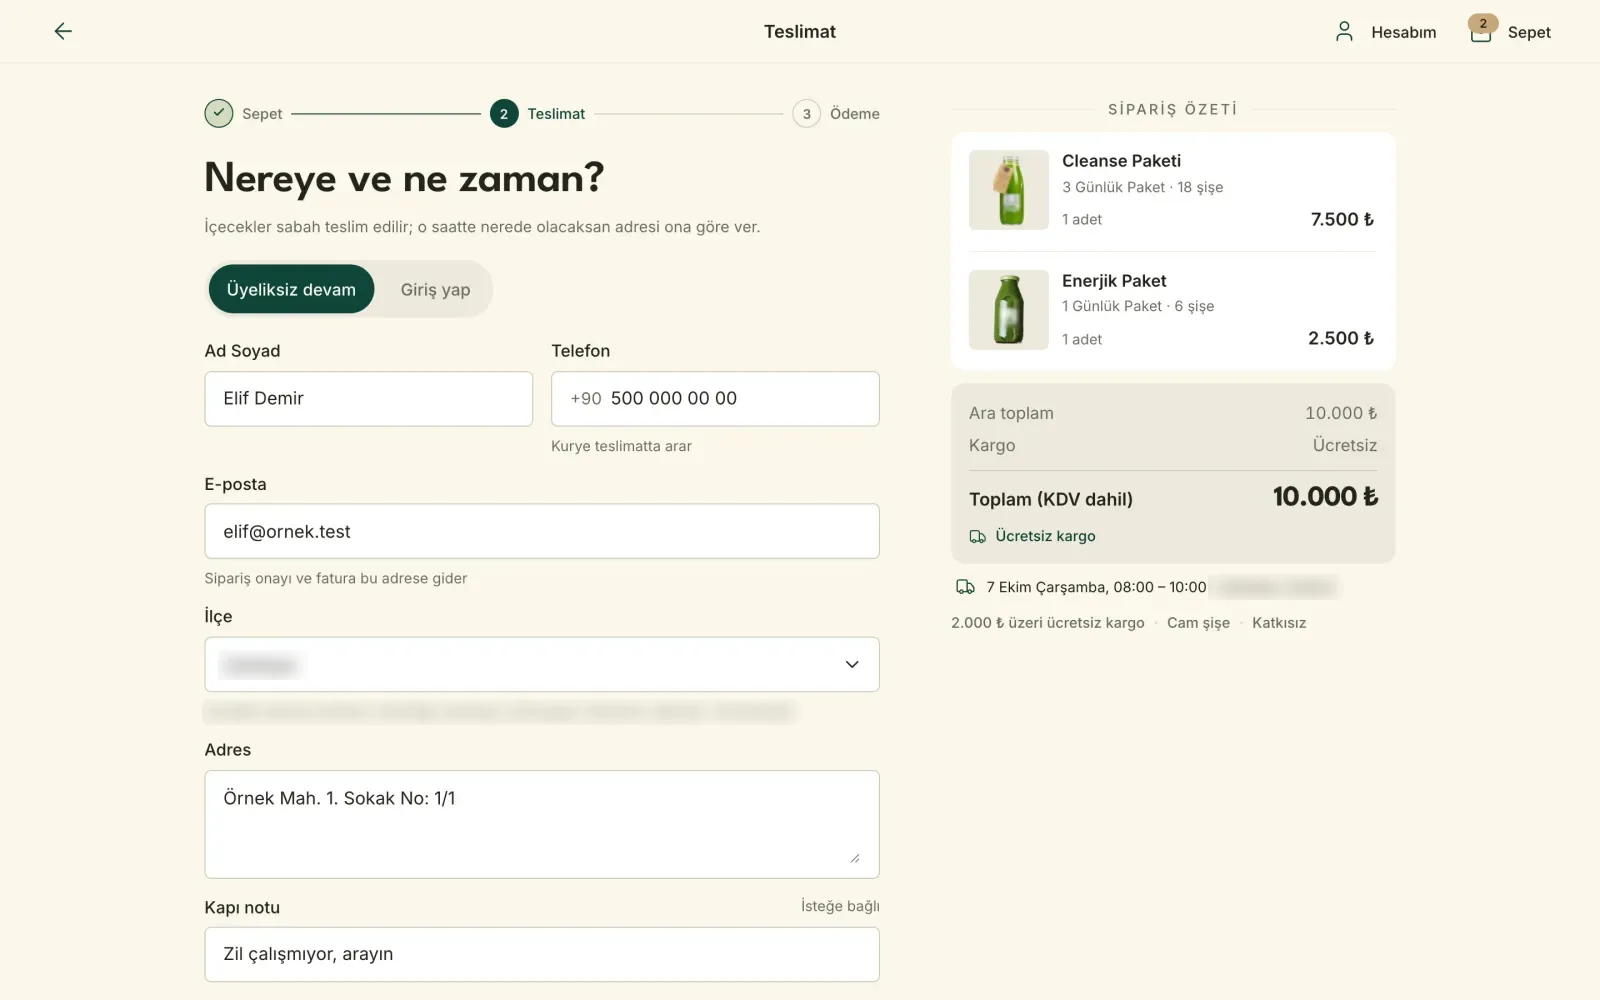
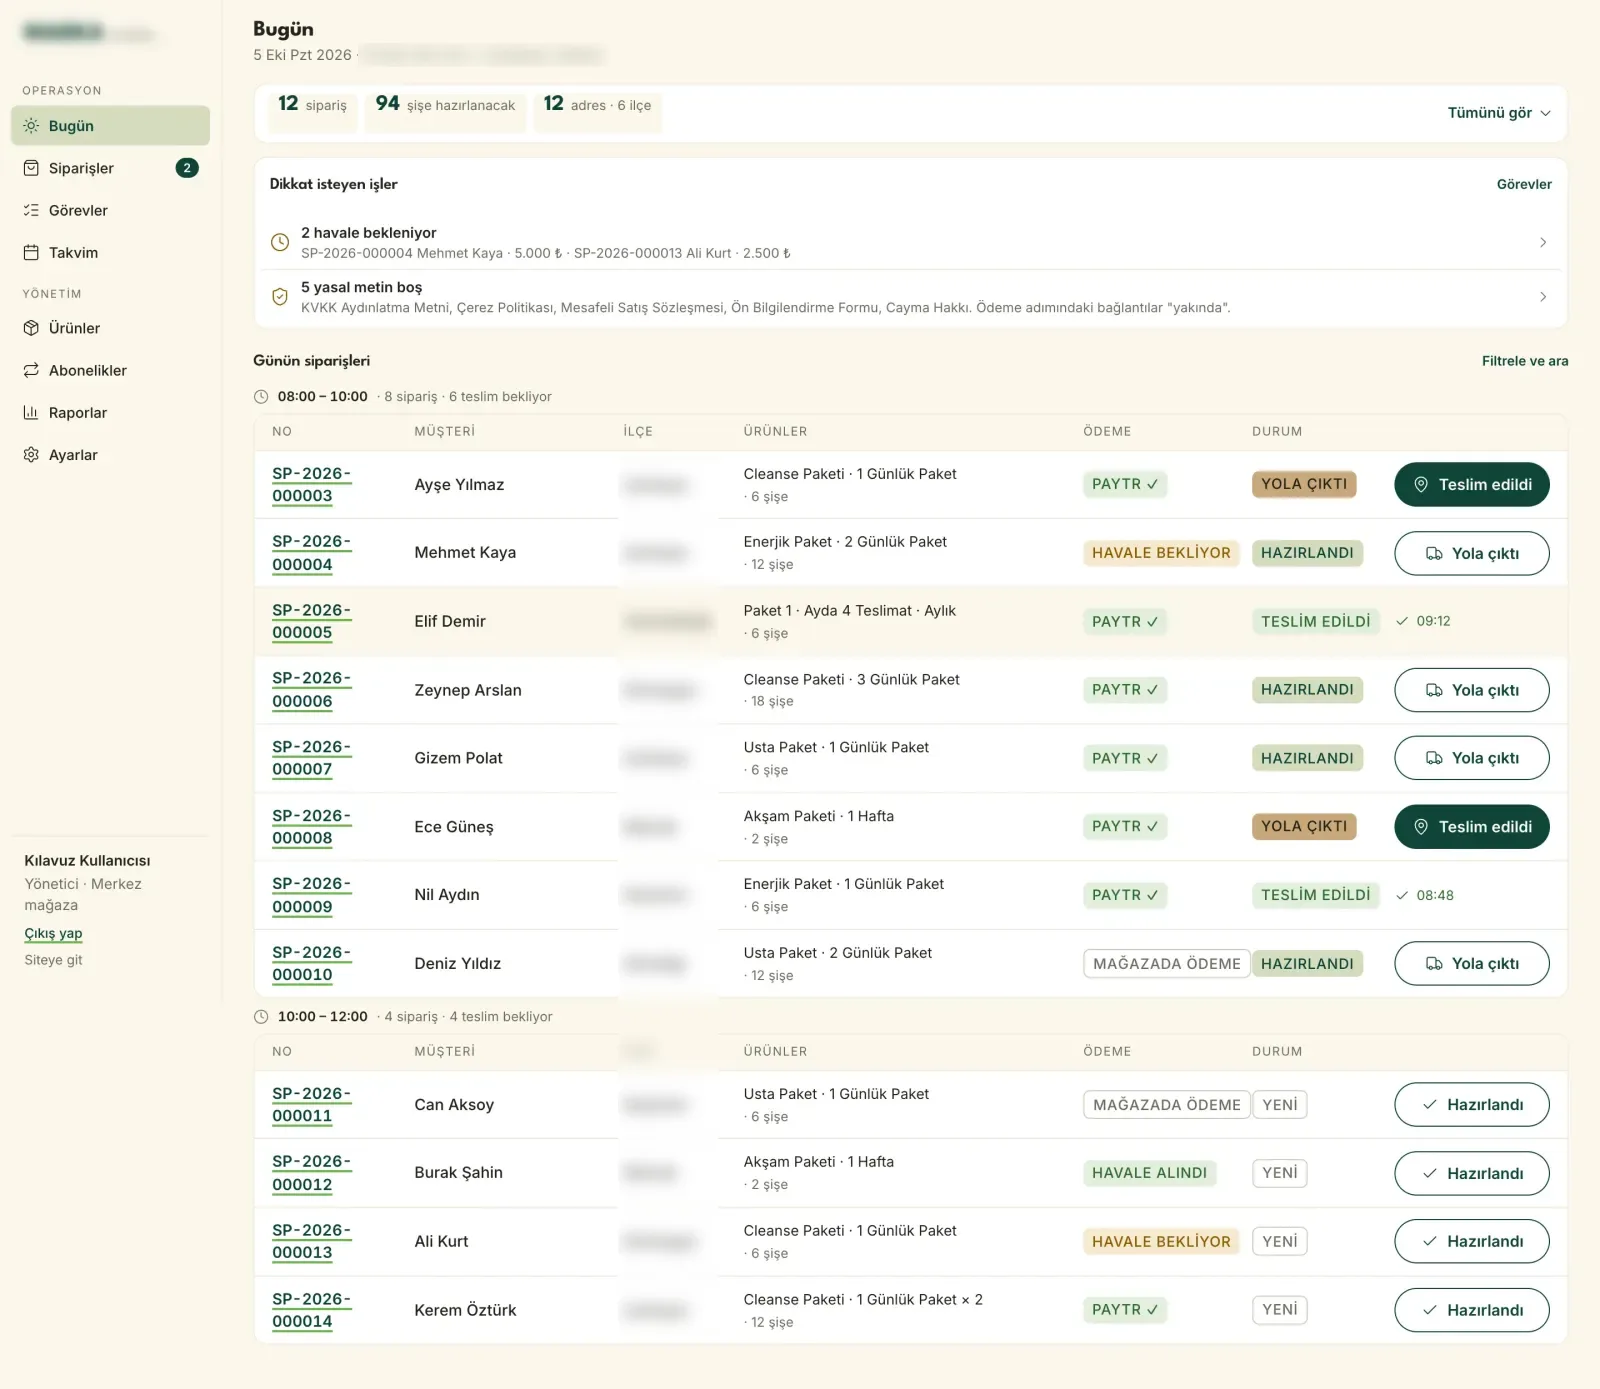
Local demo build, not yet live. Brand, labels and location details are blurred; people, orders and contact details are made up.
came in
An order site built on a ready-made theme and plugins that could not carry the rules of daily production and morning delivery.
examined
The state of the current site, competitors' order flows, delivery rules (area, day, time slot), regulatory gaps (KVKK, distance selling, food labelling) and the business's operational needs every morning.
decisions
Not classic e-commerce for a narrow range, but a storefront that leads to the sale and a panel that runs the day; a light build from scratch instead of a theme. The delivery day is chosen on the product page, checkout is three steps without an account. Scope was narrowed with cut lines; subscriptions and build-your-own packs moved to a later phase.
techniques
Laravel, Blade, Alpine.js, Tailwind, Vue + Inertia (panel), design system, delivery day and time slot rules, Pest.
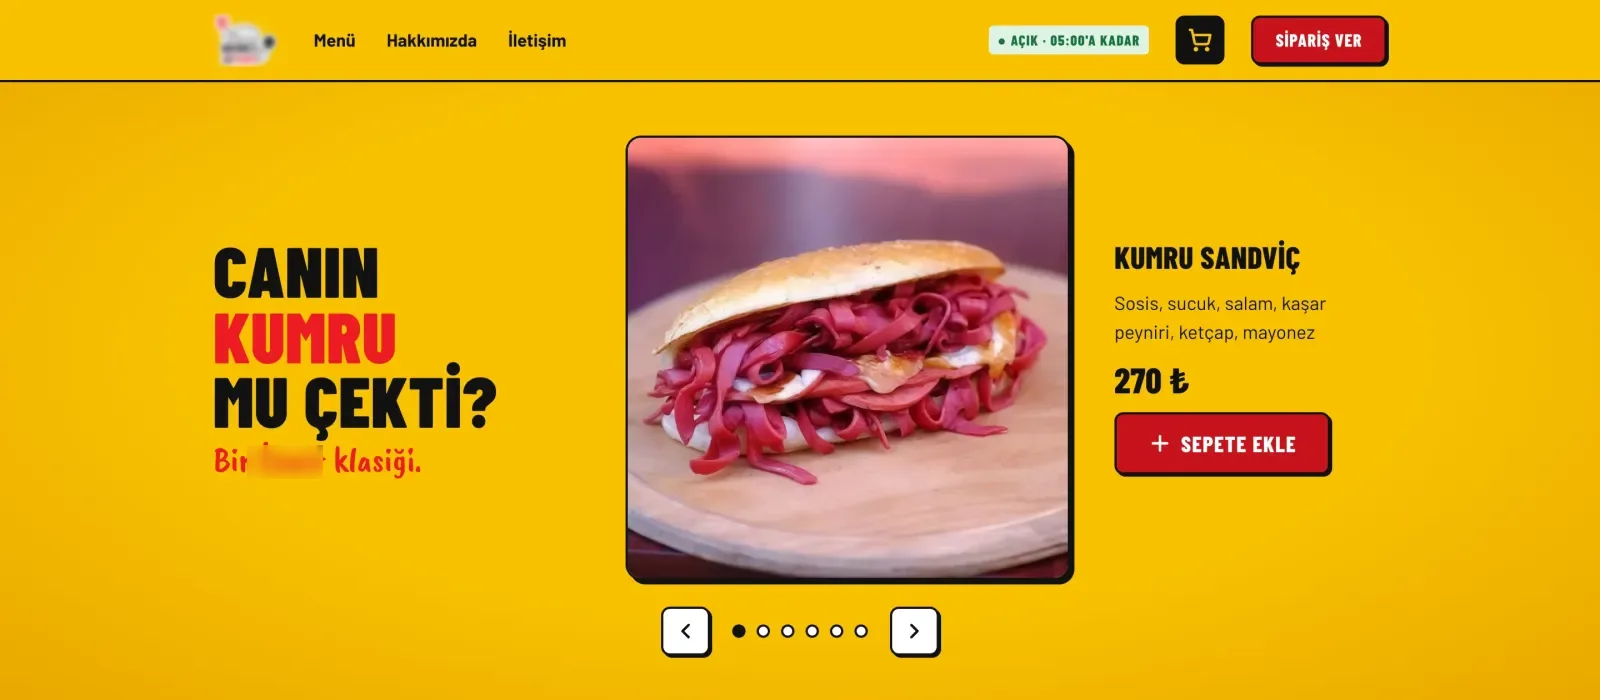
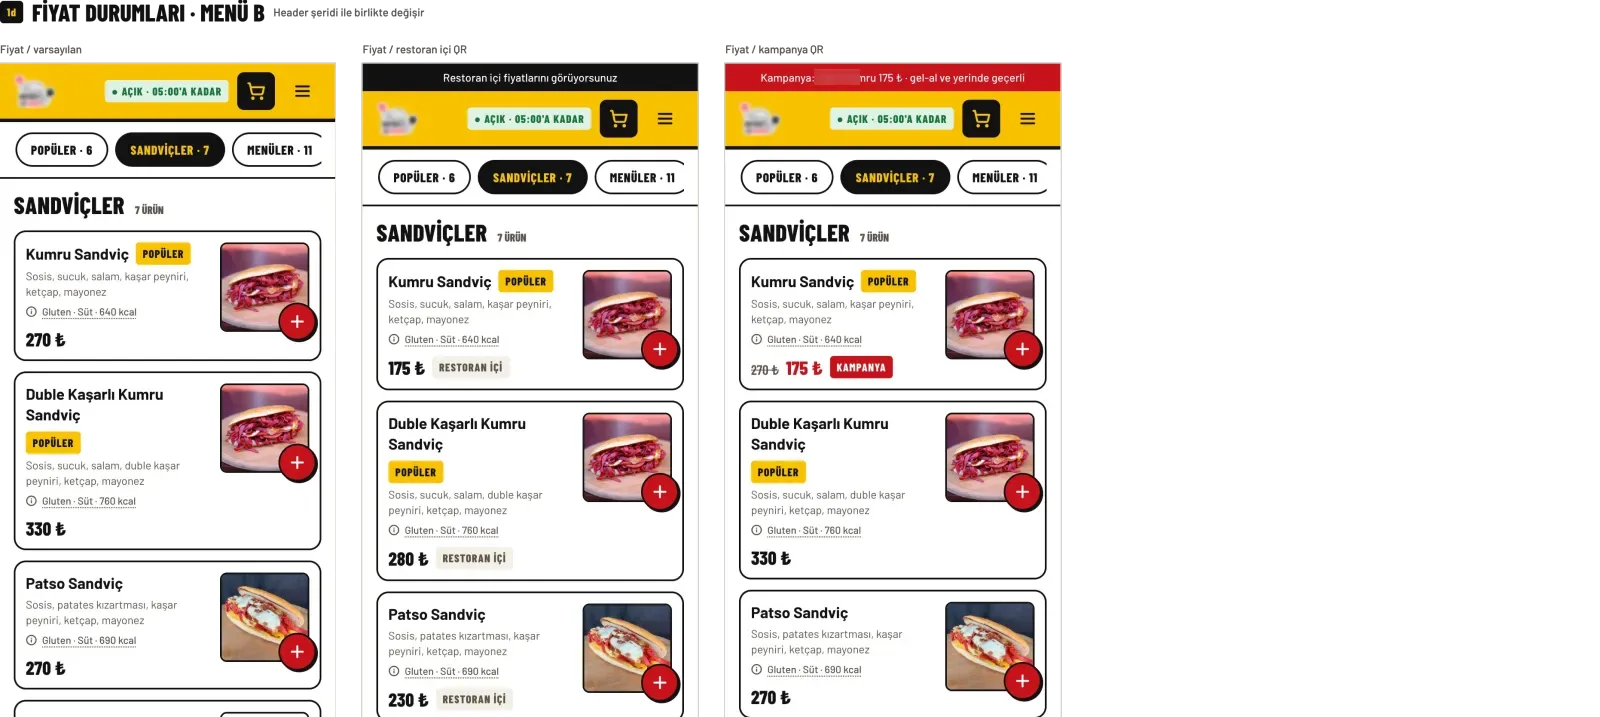
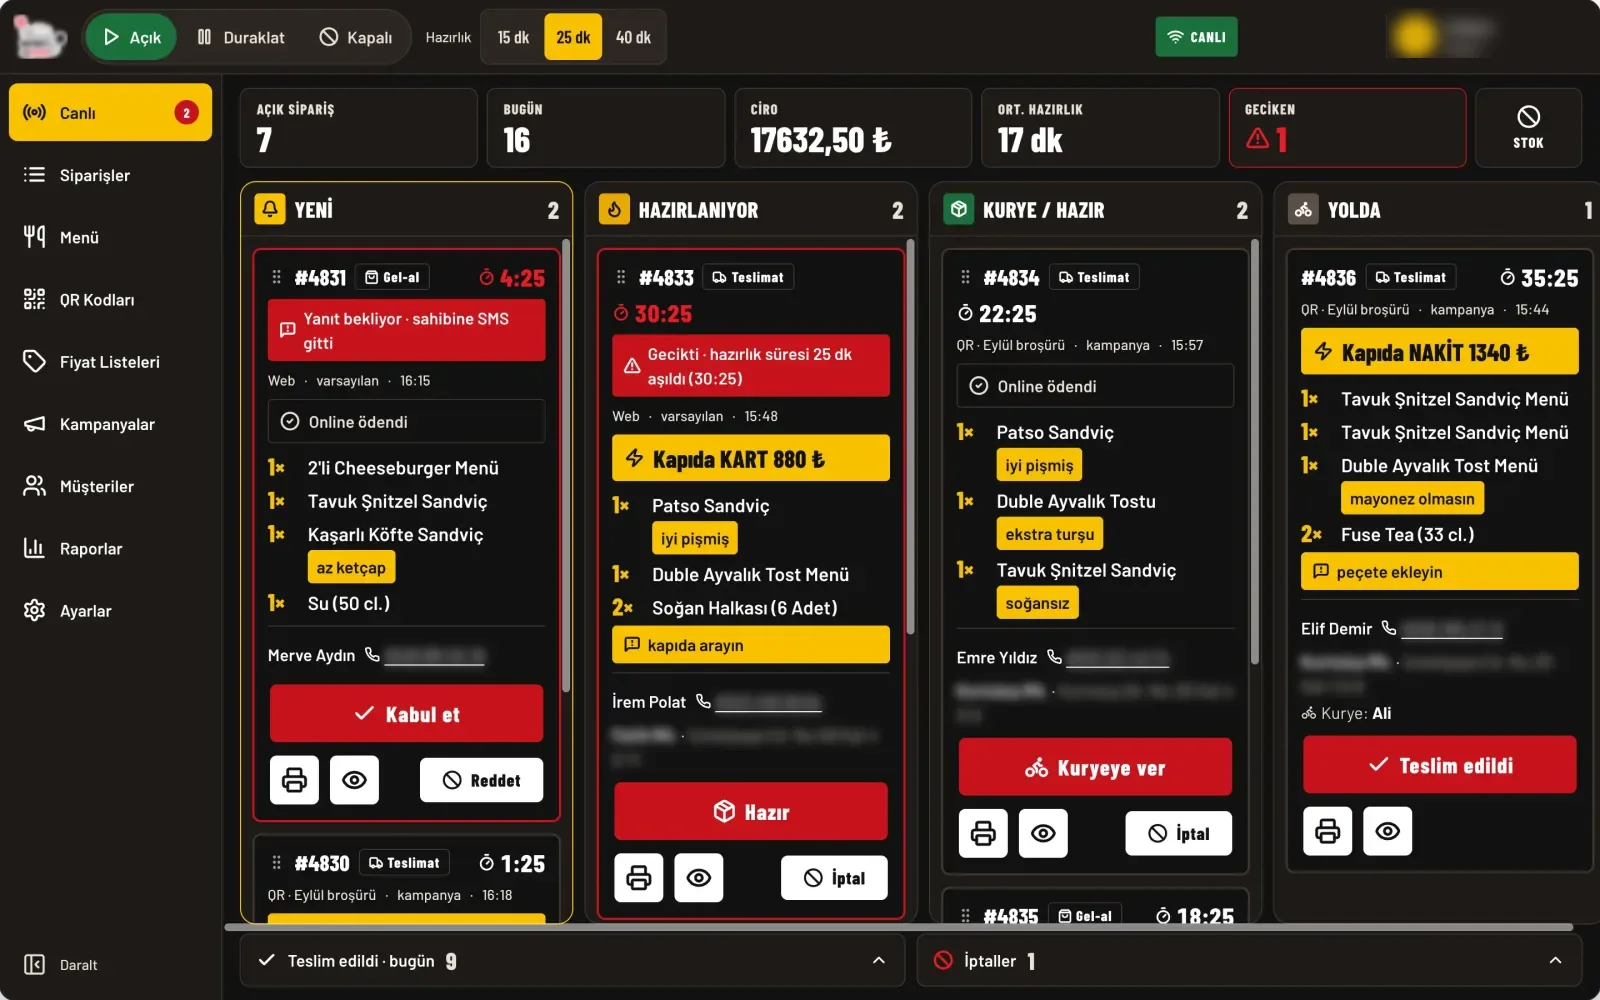
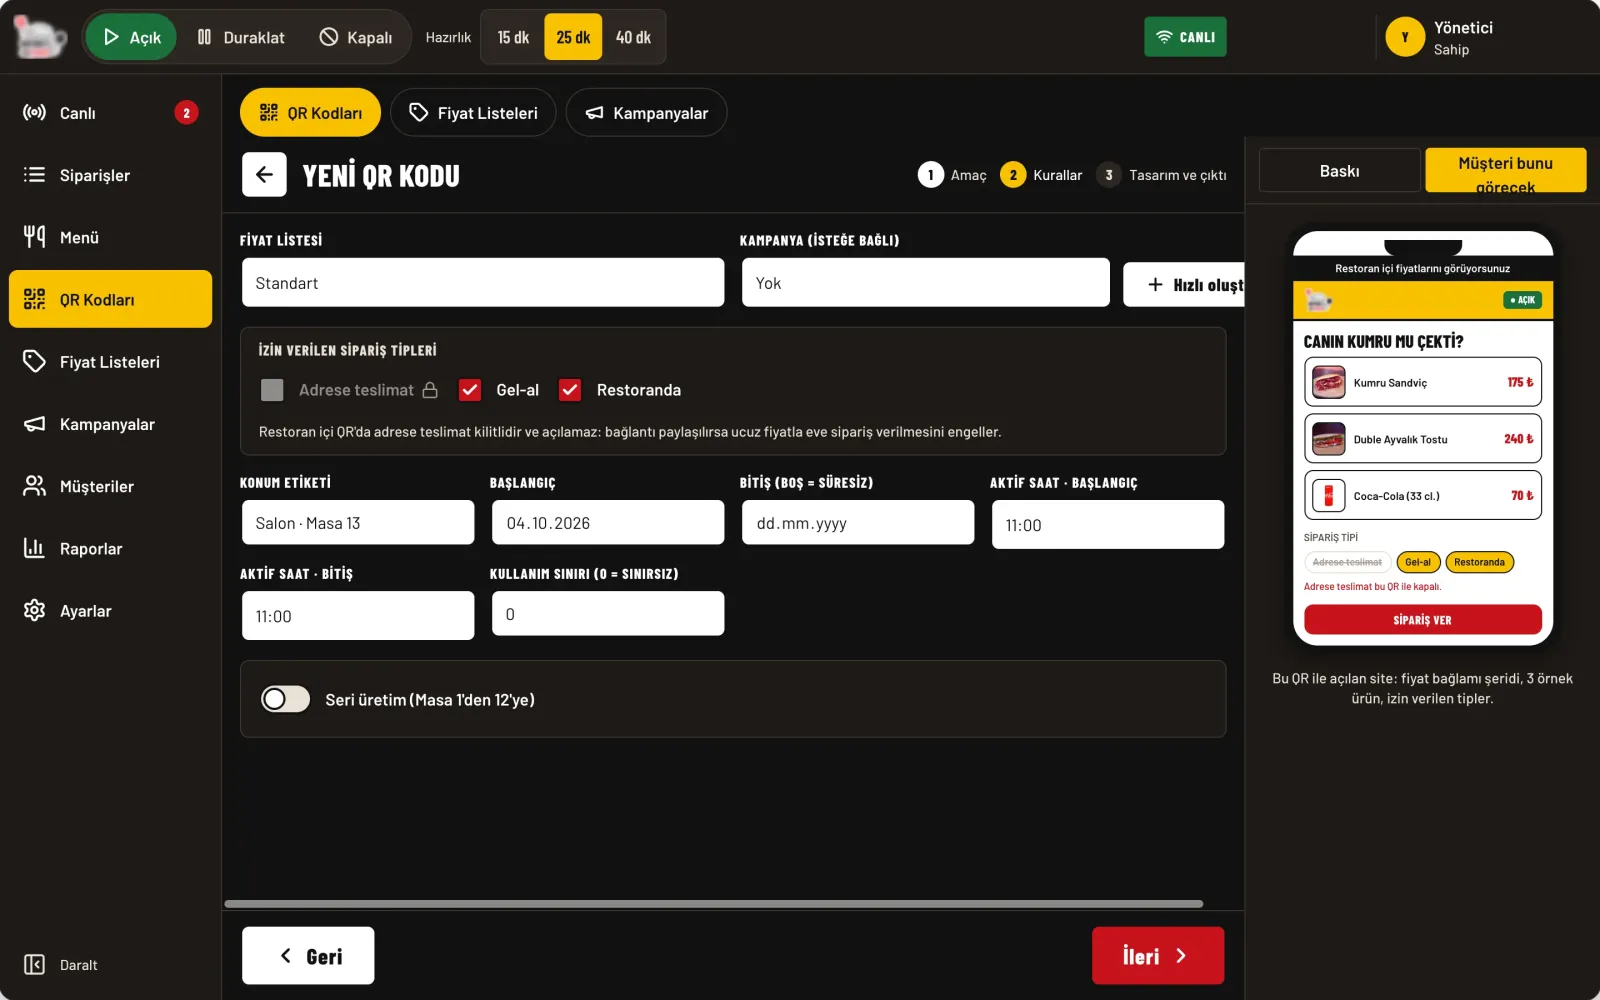
Design prototype, not live. Brand, logo, phone, address and neighbourhood are blurred; customer names and order data are samples.
came in
An ordering site of its own, and the panel that runs it, for a restaurant open late into the night whose orders were scattered across phone, messaging and delivery platforms, to reduce its dependence on the platforms.
examined
The channels orders were scattered across, table and leaflet prices that could not be managed separately, orders missed in a long night shift, distance selling, KVKK and cookie obligations.
decisions
A price context set by the QR code, from one source across every surface; delivery locked on in-restaurant QR codes; printed QR codes are archived, never deleted. A phone-first menu and checkout without an account; a calm live order screen for the night, readable from a distance, and a shift start.
techniques
Design system, design prototypes that run in the browser (target stack Laravel, Vue, PostgreSQL), dynamic QR codes, derived price lists, an 80 mm kitchen ticket.
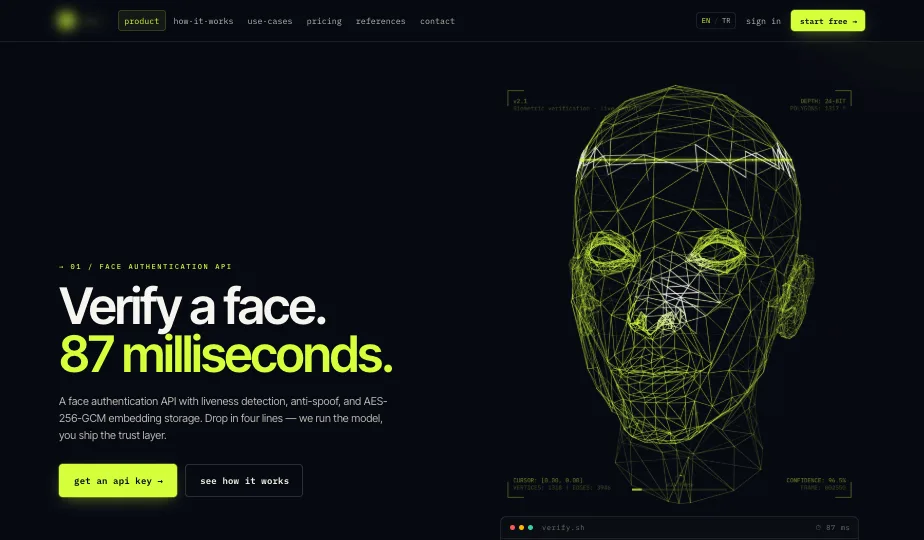
Redesign proposal, not live; the figures shown are illustrative. Brand withheld. 3D model: SamFStudent, CC BY 4.0.
came in
An API for developers to add face verification to their own apps: a two-part AI back end, liveness detection and face matching, a data model that stores no raw images, and a promotional site that speaks to developers.
examined
Which parts of the promise are measurable (latency, liveness, encryption, KVKK/GDPR), the conversion model (free API sign-up, upgrade to a paid tier, sales contact for enterprise), how the competitors (AWS Rekognition, Azure Face, FaceIO) present themselves.
decisions
The AI side is two separate parts, as in the brief; match and liveness return as two separate result fields. No images stored, only encrypted vectors. API first, then interface; a code sample on the site's first screen. The site was later reassessed; a new visual language was proposed as a clickable prototype.
techniques
Laravel API, face matching and liveness services, encrypted vector storage, webhooks; design system (Inter Tight + IBM Plex Mono, single accent), clickable prototype, a CC BY 4.0 licensed 3D wireframe model.
"Our site and products don't show up in search; our dealers do." A trade fair coming up.
examined
The existing site, the data gap between a 700+ product catalogue and the site (dimensions and colours in the PDF, absent from the site), a named competitor table, the dealer network's position in search results, the timeline against the fair.
decisions
Corporate site, technical catalogue and quote basket; dealer portal in a second phase. The document for senior management: a situation assessment with no budget and no methods.
techniques
Structured product data, technical SEO, catalogue migration, quote flow.